You signed in with another tab or window. Reload to refresh your session.You signed out in another tab or window. Reload to refresh your session.You switched accounts on another tab or window. Reload to refresh your session.Dismiss alert
{{ message }}
Repository navigation
perf(server): reuse Find documents across query changes - #29310
Changing the Find query reloads and decodes every searchable payload even when the thread has not changed. The parsed-text cache avoids Markdown parsing, but it is reached only after those reads and decodes.
Reuse the last completed rendered Find snapshot across query changes, validating the committed revision of the thread and its fork ancestors plus cwd/skill labels. Keep one snapshot, limited to 8,192 documents and 2,097,152 combined source/rendered UTF16 code units; over-budget threads keep the existing path. Source text counts toward the budget because V8 segments can retain slices of it. The existing per-query result cache retains only match metadata.
Scope
This is a focused performance fix for an obvious repeat-read defect, submitted under the small focused-fix exception; no prior maintainer approval is claimed. Search results, navigation, contracts and product defaults stay the same. It does not duplicate merged #20801, which enlarged the parsed-text cache, or open #24422, which caches timeline indexes for paging. Live PR descriptions/code searches found no query-independent Find document cache proposal. No upstream issues were inspected.
A focused baseline regression made 10 payload-batch reads for two different queries over 520 messages, expected 5. The fix makes 5. A separate red/green regression covers large hidden data-URI source text; the combined-budget test also requires counting rendered segments.
vp run check:changed: format, lint, knip, GraphQL generation, affected typechecks and adjacent tests pass. Focused Find coverage includes folded answers, plans, cwd/skills, fork ancestry, concurrent snapshot writes, streaming/rollback and cache-size fallback.
Production ProjectionStore.searchThreadStream and file-backed SQLite/WAL/reader worker, 2,600 synthetic messages/plans (859,229 source-text code units), 21 distinct queries per process, five alternating baseline/final process pairs: all 105 streamed response pairs were identical. Warm changed queries execute 0 payload batches instead of 21 and 2 SQL statements instead of 27. Median per-process warm-query medians: completion 313.67 → 28.89 ms; first frame 128.78 → 3.29 ms.
Conditions/limits: Linux aarch64, Node v26.12.1, shared 8-CPU host under substantial load (end load average 30.15/26.21/16.81). Synthetic in-process server times, not UI or production guarantees. Cold completion medians were 2,874 → 3,181 ms with wide variance; no cold-query improvement is claimed. Sampled heap observations are in the evidence, not allocation-volume measurements or a general memory claim. Cold/invalidated/oversized snapshots still hydrate payloads; continuously changing threads and cancelled scans may not benefit. The cache bounds text and items rather than exact process memory. No dev server, browser, packaged clients, paid providers or remote/tunnel transport was exercised; this changes only the server's existing search service.
Reviewed with review-loop: 2 rounds with Claude Opus 5.5 on xhigh. Reviewer verdict: approved.
Created with GPT-6.1 Sol (xhigh) in the Codex harness through T3 Code.
Macroscope's review found this PR approvable — Thread Find reuses bounded, revision-validated rendered documents when the query changes, avoiding repeated loading and parsing. The change remains confined to in-memory search optimization without changing product defaults or persistent data.
You can add or adjust custom eligibility rules. Learn more.
Reviewing files that changed from the base of the PR and between 048422e and ce03a07.
You can disable this status message by setting the reviews.review_status to false in the CodeRabbit configuration file.
Use the checkbox below for a quick retry:
Trigger review
No actionable comments were generated in the recent review.
Walkthrough
ThreadFind now reuses rendered documents across searches when the document key and source-thread revision match. It recounts results for each query and limits retained snapshots by document count and combined text length. Tests cover payload loads, cache freshness, and query results.
Changes: ThreadFind rendered-document caching
Layer / File(s)
Summary
Rendered snapshot identity and lookup apps/server/src/orchestration-v2/ThreadFind.ts, apps/server/src/orchestration-v2/ThreadFind.test.ts
ThreadFind tracks rendered snapshots by document key and source revision, and reuses cached documents when both match. A test checks file-label results after the project working directory changes.
Query recounting and bounded cache apps/server/src/orchestration-v2/ThreadFind.ts, apps/server/src/orchestration-v2/ThreadFind.test.ts
Search recounts matches for the current query and retains rendered documents only within the document-count and combined-length limits. Tests check payload-load counts and query results across search scenarios.
sequenceDiagram
  participant Search caller
  participant ThreadFind
  participant Rendered snapshot
  participant Payload loader
  Search caller->>ThreadFind: Submit search query
  ThreadFind->>Rendered snapshot: Check document key and source revision
  alt Snapshot matches
    Rendered snapshot-->>ThreadFind: Return rendered documents
  else Snapshot does not match
    ThreadFind->>Payload loader: Load payloads
    Payload loader-->>ThreadFind: Return payloads
  end
  ThreadFind->>ThreadFind: Count matches for query
  ThreadFind-->>Search caller: Return search results
Loading
Possibly related issues
pingdotgg/t3code#9661: The issue identifies chat search scans as a performance target. This change reuses rendered documents across query changes, but does not implement the reported result-limit change.
Suggested reviewers:juliusmarminge
Merge Risk: Minimal · previous review 04842
Find now reuses rendered documents when only the query changes, which reduces payload reads on repeated searches. The reviewed change shows no concrete merge-blocking risk. The author did not test native, packaged or remote clients, and large-thread memory use is only bounded by the cache limits.
Pre-merge checks: 4
Check name
Status
Explanation
Title check
The title is concise, conventional, and clearly identifies the main change: reusing Find documents across query changes.
Description check
The description is mostly complete. It explains the problem, implementation, scope exception, verification results, limitations, and agent usage. It uses “Scope” and “Proof” headings instead of the te…
Linked Issues check
Check skipped because no linked issues were found for this pull request.
Out of Scope Changes check
Check skipped because no linked issues were found for this pull request.
Full details: Description check
Explanation
The description is mostly complete. It explains the problem, implementation, scope exception, verification results, limitations, and agent usage. It uses “Scope” and “Proof” headings instead of the template’s exact “Scope and approval” and “Verification” headings, but the required information is present.
Finishing Touches
Generate unit tests (beta)
Create a new PR
Autofix · Keep fixing CodeRabbit findings and required CI, and resolving merge conflicts
Included review availability: This review used your included allowance. Your plan provides up to 10 included reviews per hour; 7 remain after this review.
merged current main (f31ce3eeb5) with merge commit 048422e7a3eea1edf6bdc661642b63a6580ee6c3. resolved the ThreadFind conflict by keeping main's run-aware folded-answer filtering and this pr's rendered-document reuse. the pr still changes only the two ThreadFind files. github reports no conflicts. two independent read-only reviews approved this head with no findings.
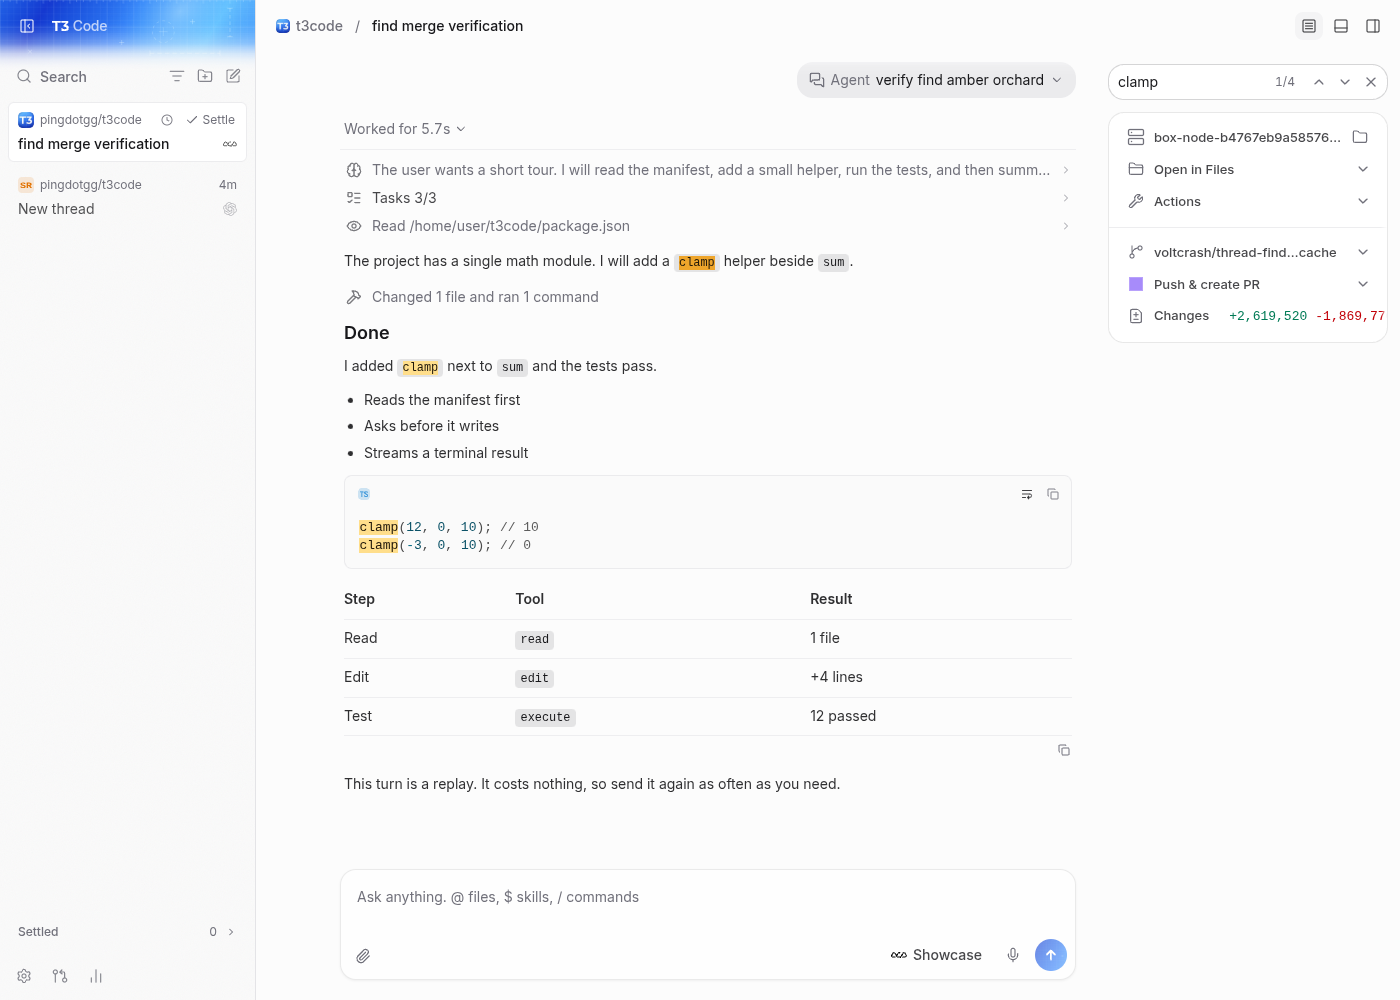
verified this head in the real dev web client through the replay provider and Playwright with system Chrome: changing queries returned 4 matches for clamp, 1 for replay, 0 for absent sapphire, and 4 after returning to clamp. next moved to 2/4 and previous returned to 1/4.
verification is waiting: github Actions workflows are queued with no jobs started, and the dedicated blacksmith worker remained queued for over 15 minutes. vp i && vp run check:changed was submitted through blacksmith-check but did not start. typecheck, lint and tests on this head remain unverified. the latest CodeRabbit check passed with no actionable findings. no performance claim or new UI change is included.
previous takeover verification (historical):
Merged current main
30de87daa2 merges github/main (0815d98cd7) with a merge commit. It conflicted with #34132, which moved Find's caches into an RcRef that is dropped after one idle minute. The resolution keeps that change and moves this PR's rendered-document snapshot into the same RcRef, so reused documents are also freed when Find goes idle. Text caches are now read as textCache.text / textCache.largeText. Nothing else changed.
vp run check:changed passed through blacksmith-check: format, lint, knip, graphql, typecheck (3 packages), and tests (ThreadFind.test.ts 21/21, including main's idle-eviction case, plus AgentContextBudget.test.ts).
Not re-verified in a running client after the merge. The runtime check below was on the earlier head 4971ecf.
Verified in a real dev environment
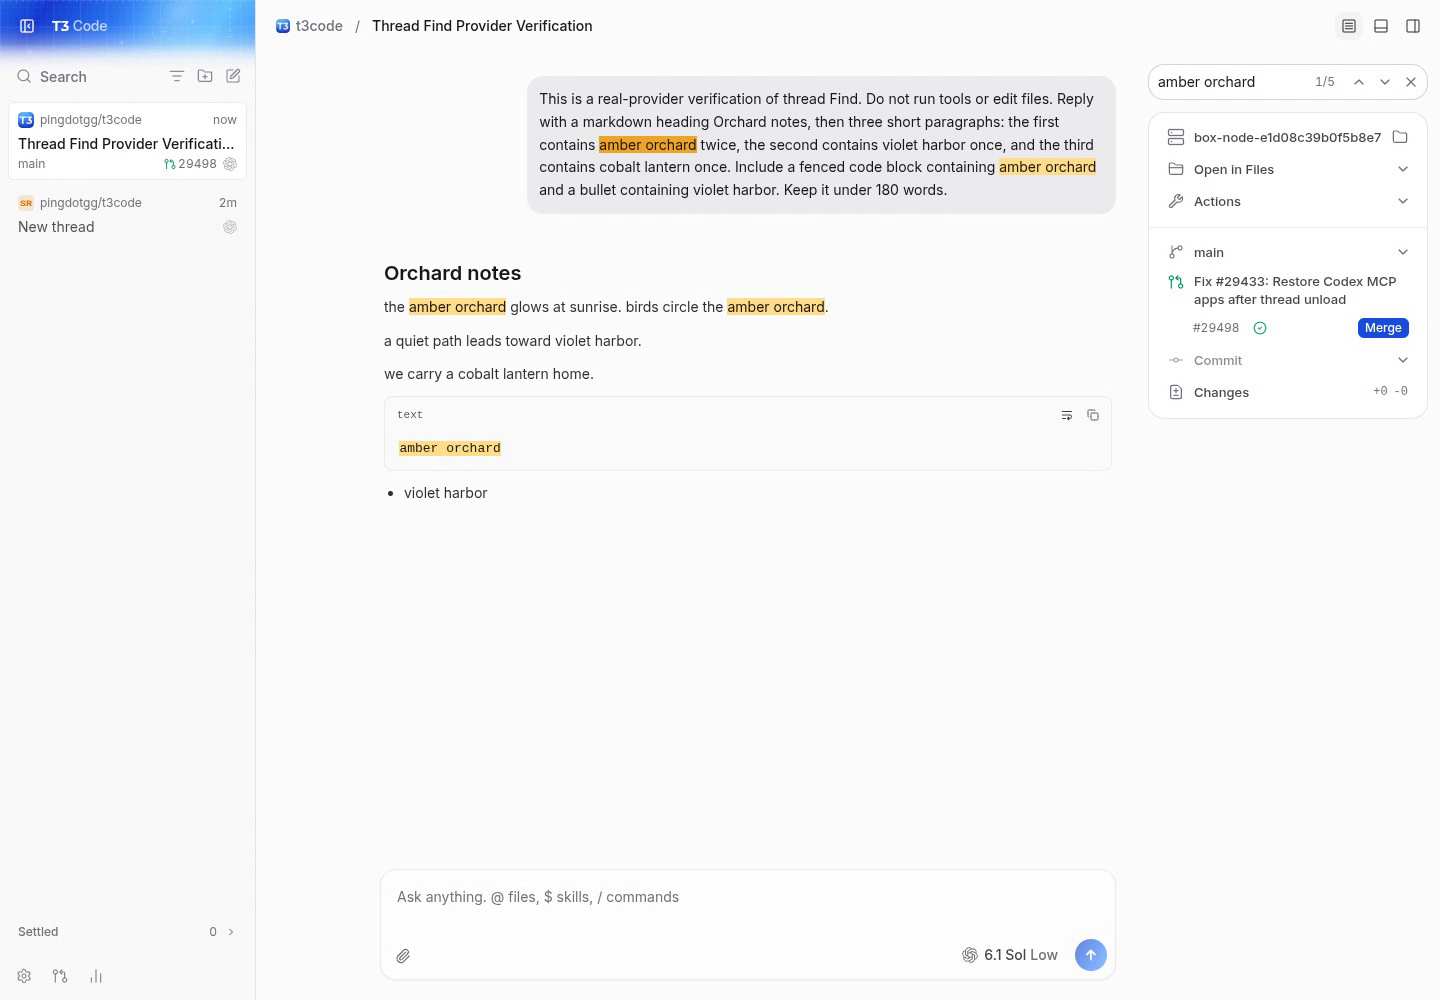
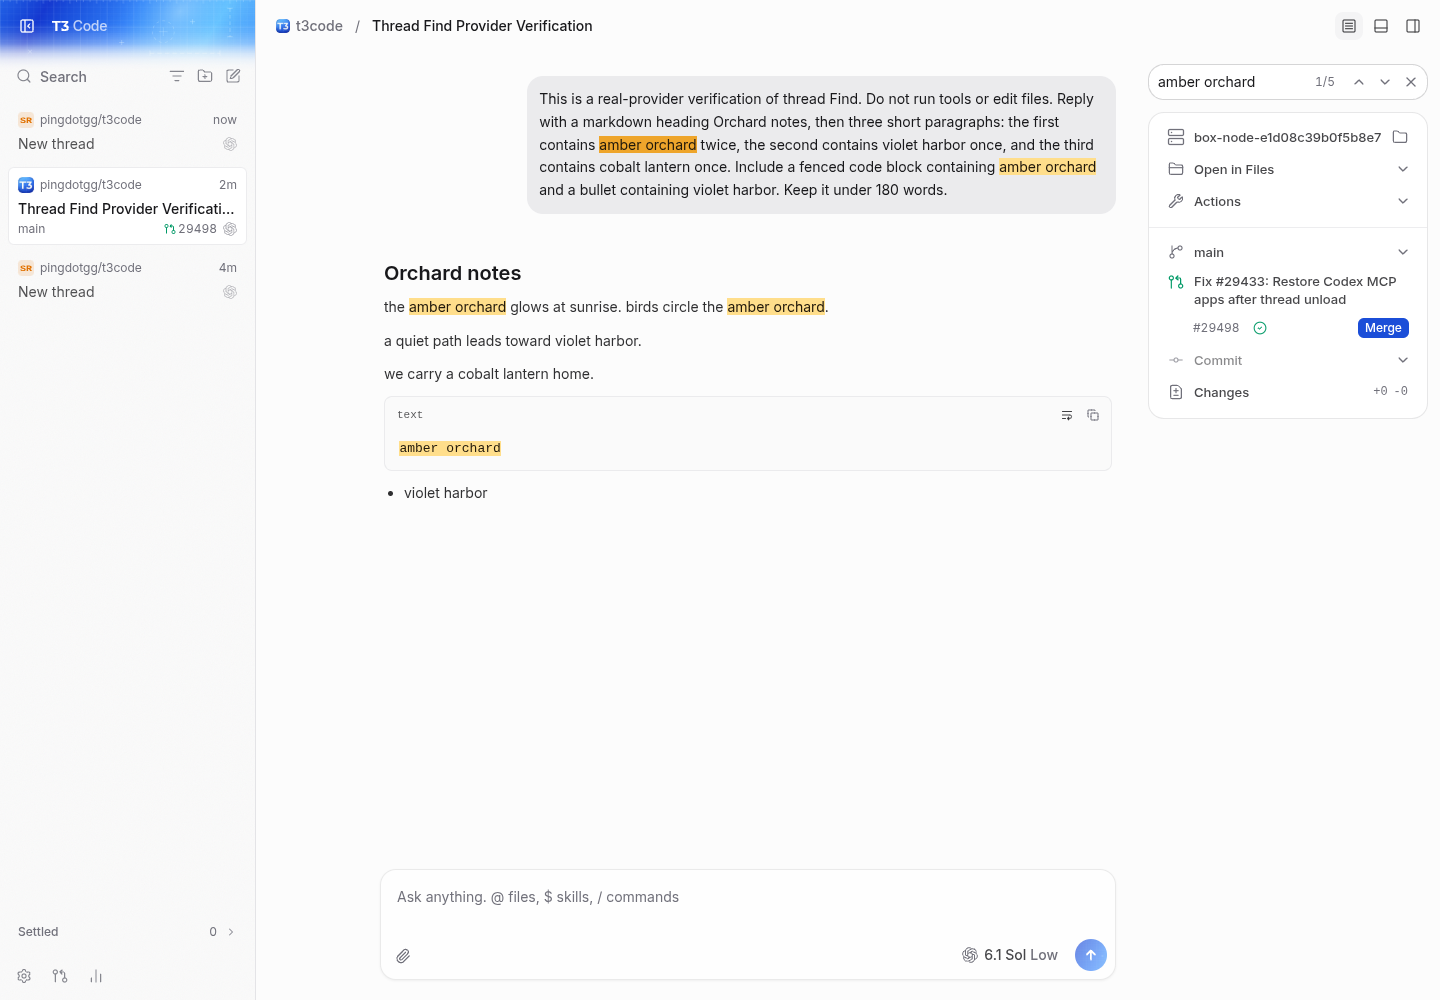
verified exact head 4971ecfb4d8c469cfc6d288333394ded006d3690 on a linux boat vm using the real dev web app, repository playwright, and /usr/bin/google-chrome. created the repository project and conversation through the app and ran real codex gpt-6.1-sol turns through the local proxy. no mocks or seeded fixtures.
reproduced the repeat reads on github/main at a03648901640216a154d387cfb2cdec268e6527e, then stopped main and ran the pr against a copy of that isolated conversation. the same five ui searches returned the same counts:
query             main  pr
amber orchard        5   5
violet harbor        4   4
cobalt lantern       2   2
absent sapphire      0   0
amber orchard        5   5

successful ThreadFind.load spans in the unmodified server trace:
main: 4 payload-batch loads
pr:   1 payload-batch load
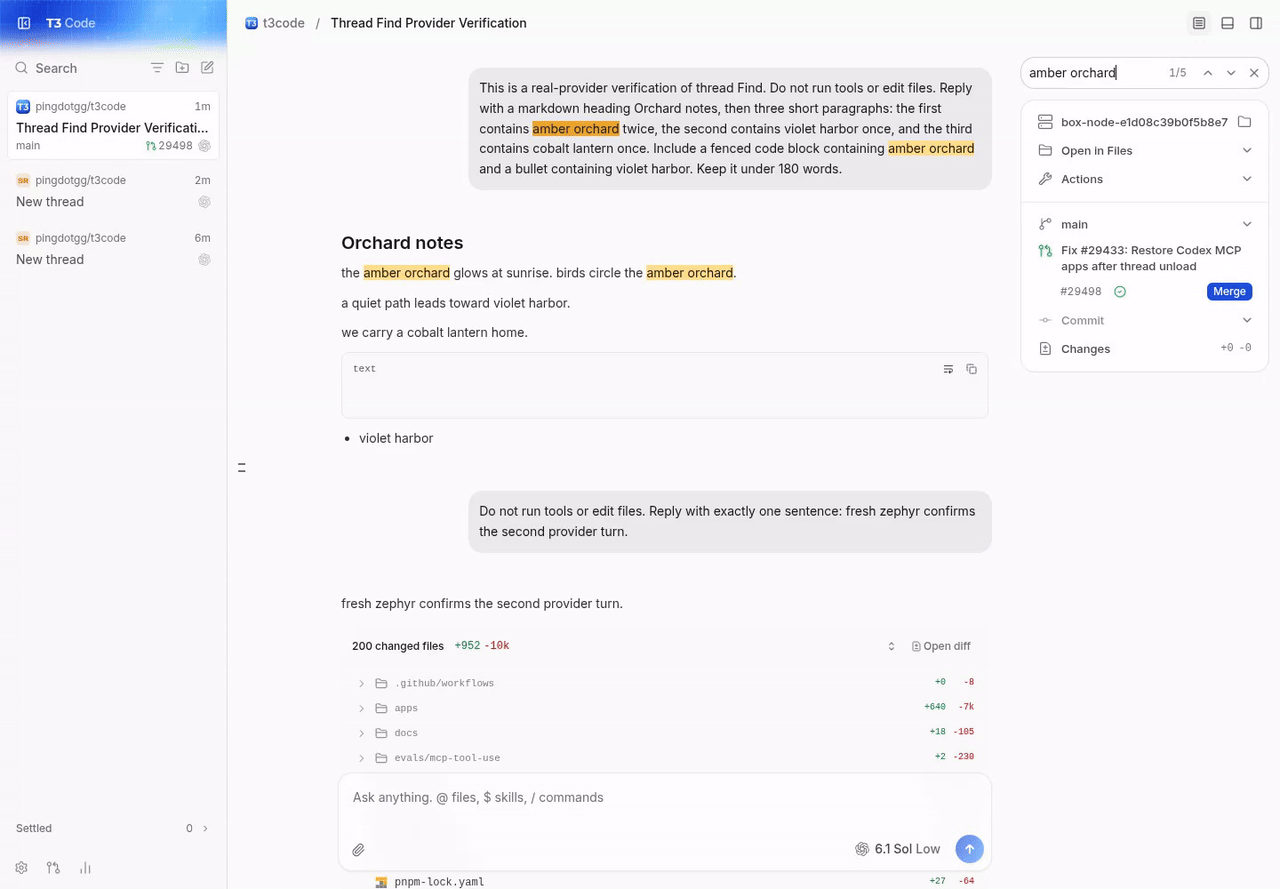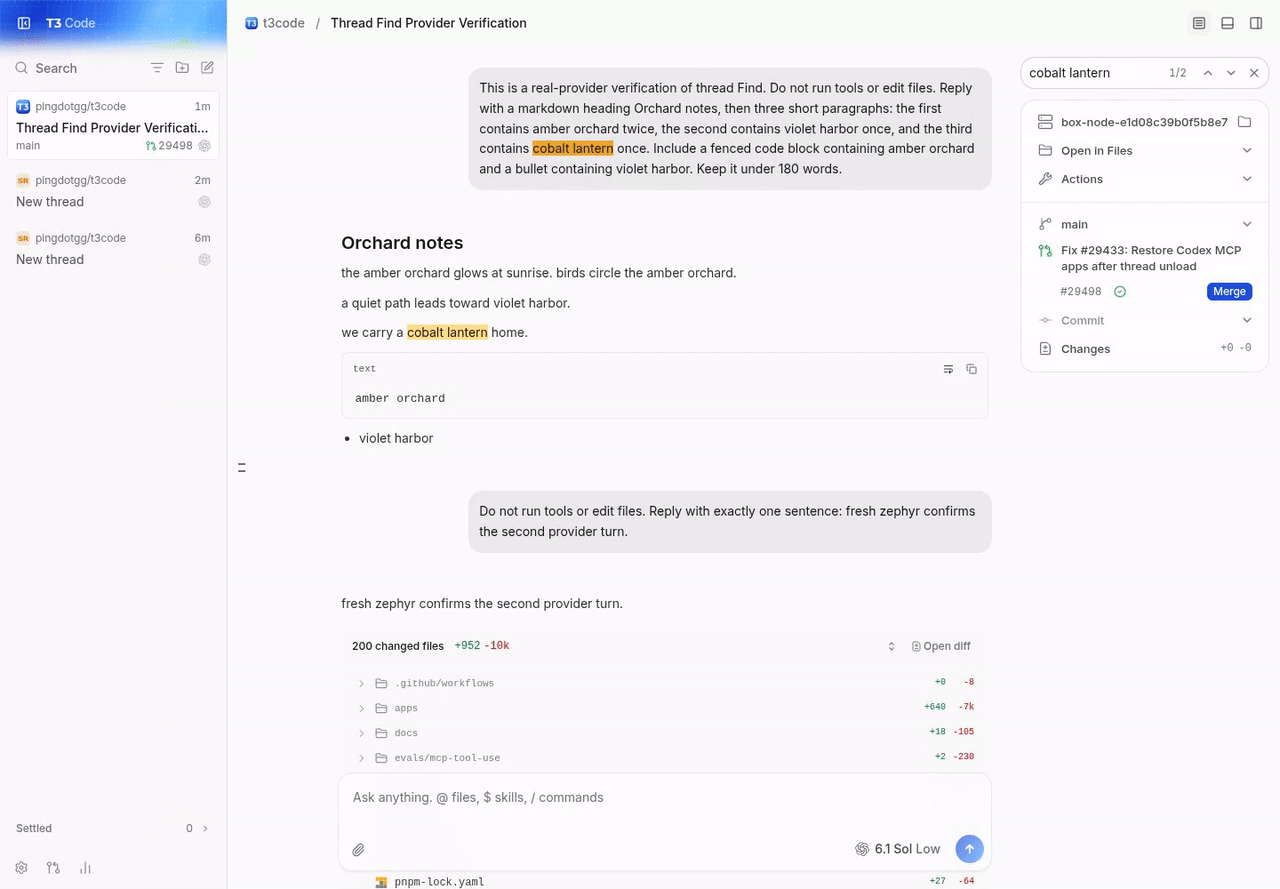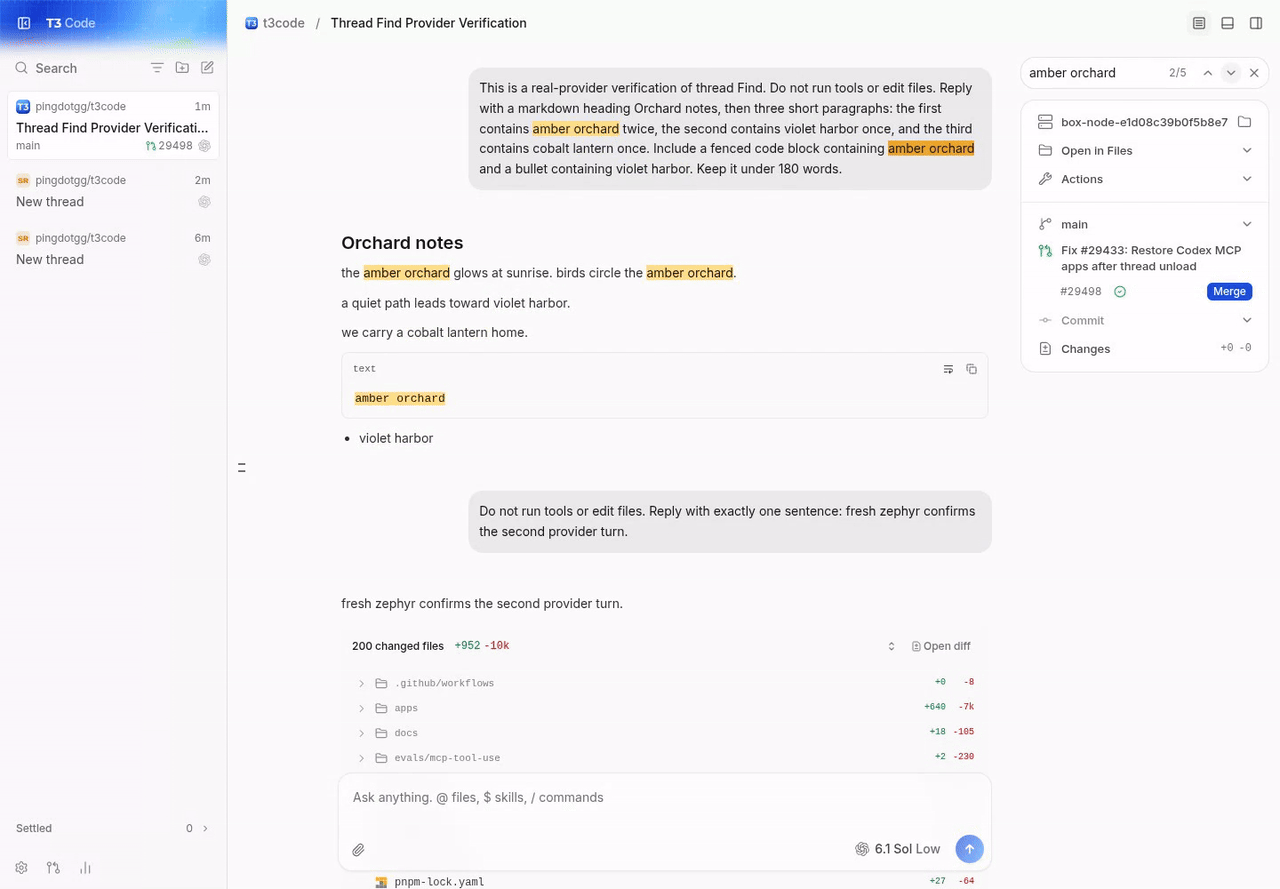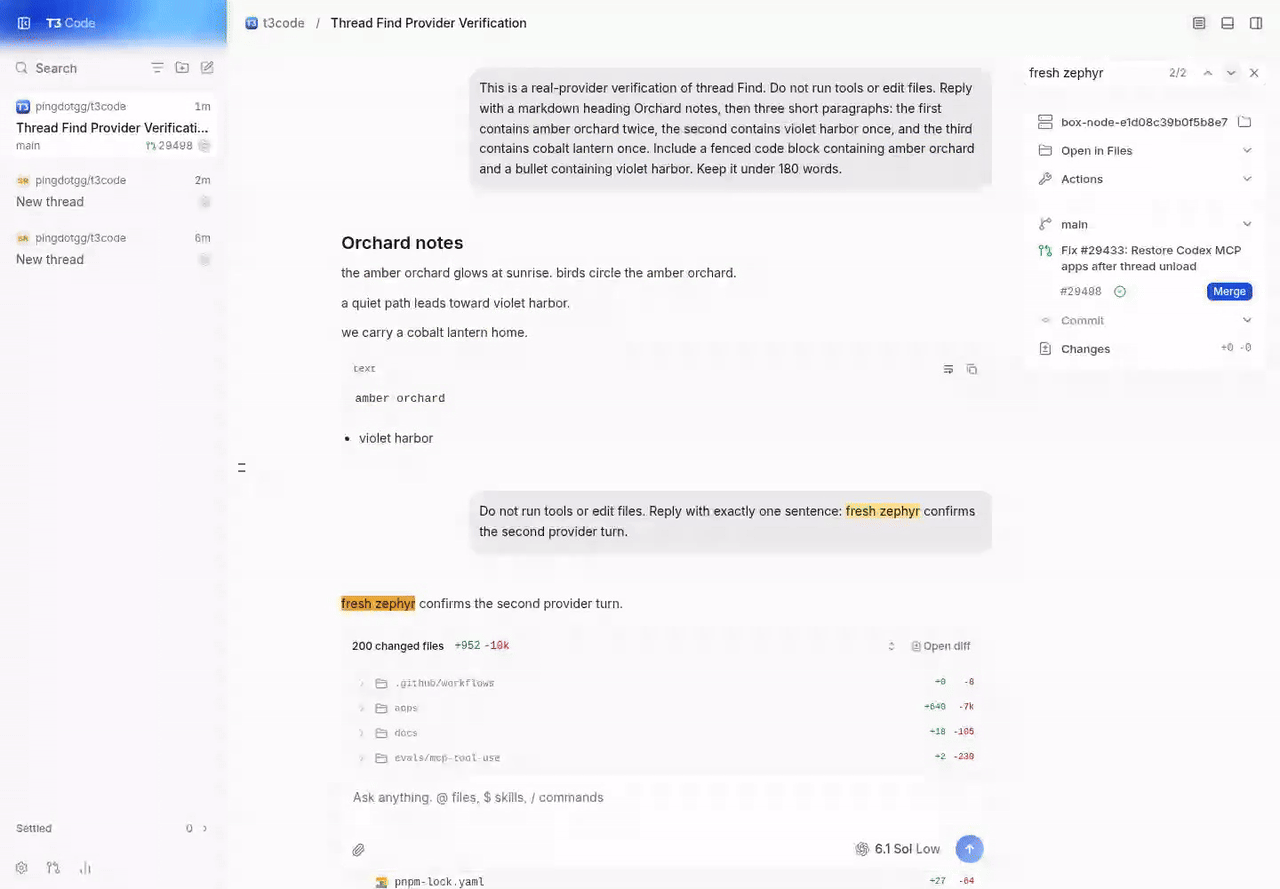
match navigation, wraparound, keyboard navigation, zero results, and searching prompt/prose/code/bullet text worked. after caching zero matches for fresh zephyr, a second real provider turn added that phrase in its prompt and reply. the same query then found both matches and navigated between them.
vp run check:changed 47f2c8d29e981c7723467efe137ee19e91df924e passed through blacksmith-check: format, lint, knip, graphql, affected typechecks, and 21 tests. the focused find suite also passed all 20 tests. no source changes or pushes were needed.
native ios/android and packaged desktop clients, remote/relay/tunnel connections, and other providers were not exercised. large-thread memory bounds, concurrent scans, fork ancestry, rollback, and cwd/skill-label invalidation were not exercised in the running client; existing focused tests cover several of those cases. this small real conversation proves payload reuse and search correctness, not a production latency or memory improvement.
This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters.
Learn more about bidirectional Unicode characters
size:M30-99 changed lines (additions + deletions).vouch:unvouchedPR author is not yet trusted in the VOUCHED list.
2 participants
Add this suggestion to a batch that can be applied as a single commit.This suggestion is invalid because no changes were made to the code.Suggestions cannot be applied while the pull request is closed.Suggestions cannot be applied while viewing a subset of changes.Only one suggestion per line can be applied in a batch.Add this suggestion to a batch that can be applied as a single commit.Applying suggestions on deleted lines is not supported.You must change the existing code in this line in order to create a valid suggestion.Outdated suggestions cannot be applied.This suggestion has been applied or marked resolved.Suggestions cannot be applied from pending reviews.Suggestions cannot be applied on multi-line comments.Suggestions cannot be applied while the pull request is queued to merge.Suggestion cannot be applied right now. Please check back later.




Changing the Find query reloads and decodes every searchable payload even when the thread has not changed. The parsed-text cache avoids Markdown parsing, but it is reached only after those reads and decodes.
Reuse the last completed rendered Find snapshot across query changes, validating the committed revision of the thread and its fork ancestors plus cwd/skill labels. Keep one snapshot, limited to 8,192 documents and 2,097,152 combined source/rendered UTF16 code units; over-budget threads keep the existing path. Source text counts toward the budget because V8 segments can retain slices of it. The existing per-query result cache retains only match metadata.
Scope
This is a focused performance fix for an obvious repeat-read defect, submitted under the small focused-fix exception; no prior maintainer approval is claimed. Search results, navigation, contracts and product defaults stay the same. It does not duplicate merged #20801, which enlarged the parsed-text cache, or open #24422, which caches timeline indexes for paging. Live PR descriptions/code searches found no query-independent Find document cache proposal. No upstream issues were inspected.
Proof
Reproduction driver, raw results, red/green logs and review ledger.
vp run check:changed: format, lint, knip, GraphQL generation, affected typechecks and adjacent tests pass. Focused Find coverage includes folded answers, plans, cwd/skills, fork ancestry, concurrent snapshot writes, streaming/rollback and cache-size fallback.ProjectionStore.searchThreadStreamand file-backed SQLite/WAL/reader worker, 2,600 synthetic messages/plans (859,229 source-text code units), 21 distinct queries per process, five alternating baseline/final process pairs: all 105 streamed response pairs were identical. Warm changed queries execute 0 payload batches instead of 21 and 2 SQL statements instead of 27. Median per-process warm-query medians: completion 313.67 → 28.89 ms; first frame 128.78 → 3.29 ms.Conditions/limits: Linux aarch64, Node v26.12.1, shared 8-CPU host under substantial load (end load average 30.15/26.21/16.81). Synthetic in-process server times, not UI or production guarantees. Cold completion medians were 2,874 → 3,181 ms with wide variance; no cold-query improvement is claimed. Sampled heap observations are in the evidence, not allocation-volume measurements or a general memory claim. Cold/invalidated/oversized snapshots still hydrate payloads; continuously changing threads and cancelled scans may not benefit. The cache bounds text and items rather than exact process memory. No dev server, browser, packaged clients, paid providers or remote/tunnel transport was exercised; this changes only the server's existing search service.
Reviewed with review-loop: 2 rounds with Claude Opus 5.5 on xhigh. Reviewer verdict: approved.
Created with GPT-6.1 Sol (xhigh) in the Codex harness through T3 Code.